Action generation
The policy predicts robot targets and independent left- and right-jaw commands. These visualizations replay the original checkpoint on recorded observations.
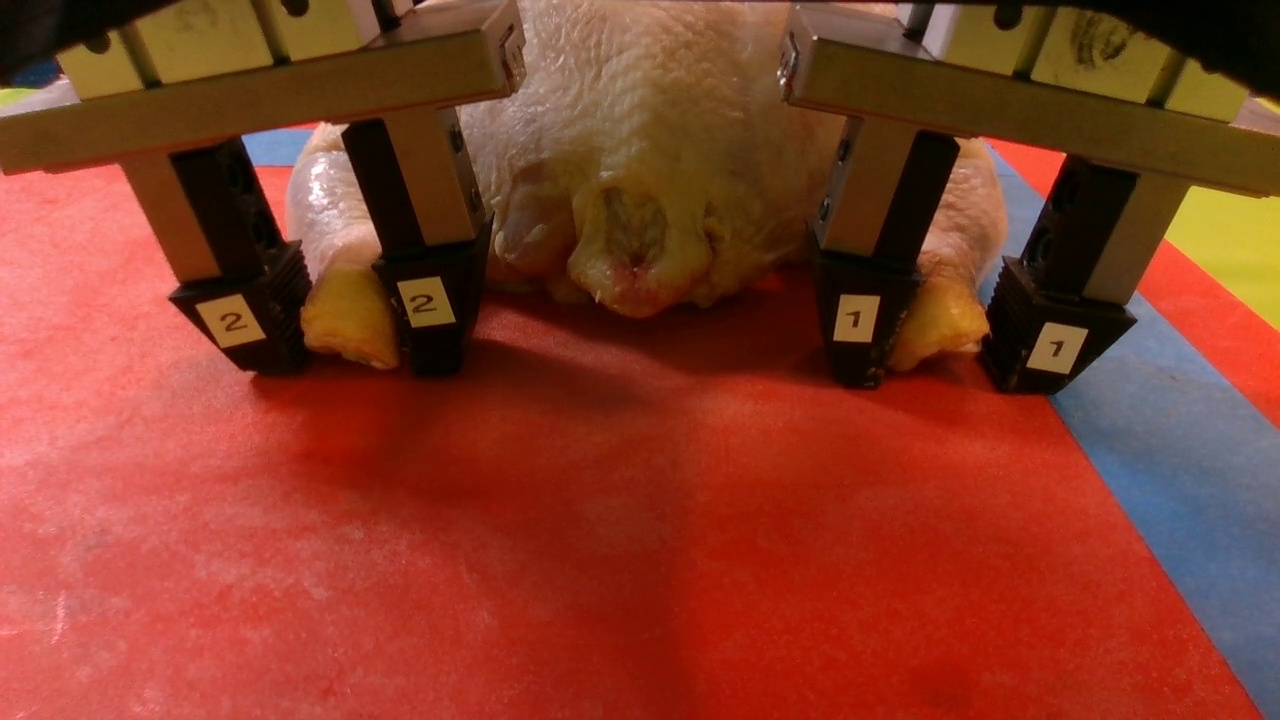
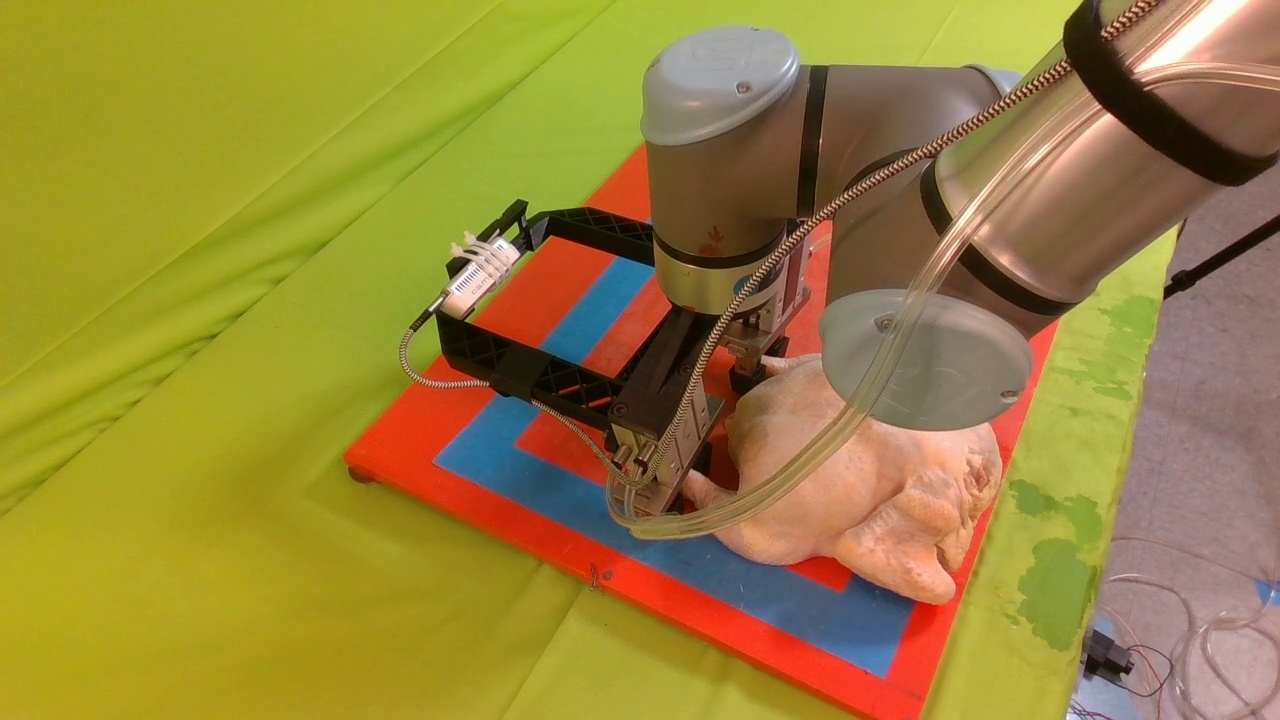
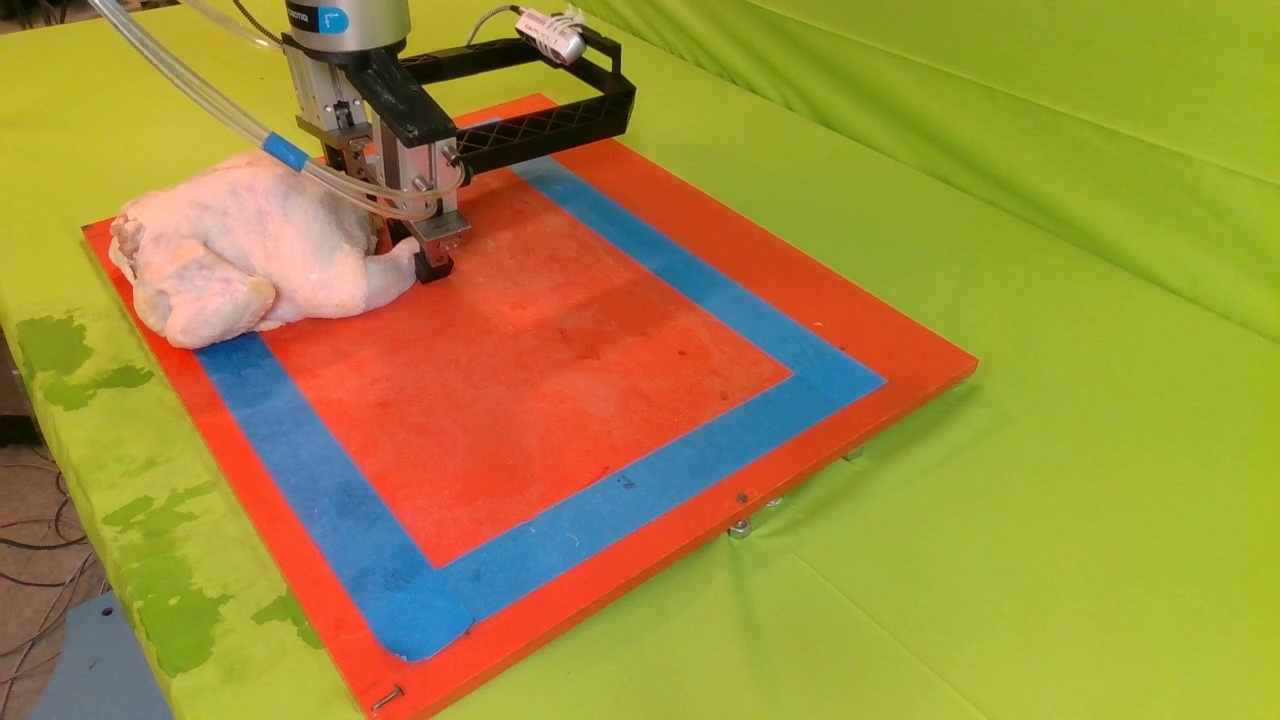
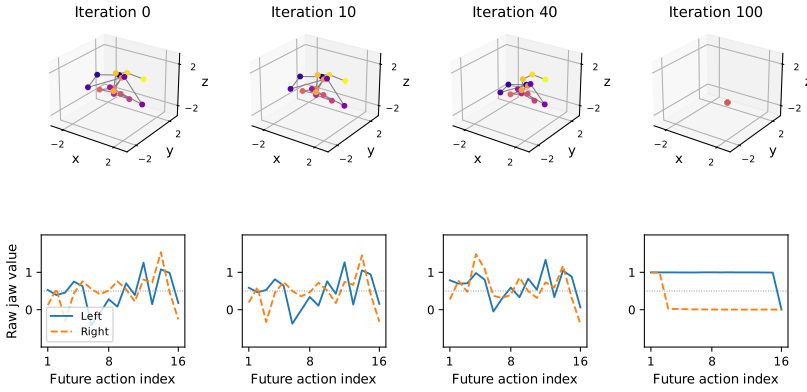
At three pauses, six candidate action sequences are refined over 16 DDIM iterations. Color marks future action index; the inset shows raw jaw values. The plans are new offline outputs, approximately projected into the camera view. Resuming footage shows the original recording.
Browse 23 individual action videos · Replay and projection details
Diffusion-policy outputs
The numerical explorer below uses a separate replay with the checkpoint’s original 100-iteration setting. It shows the recorded intermediate model values, including the raw jaw predictions.
16 future steps
EMA checkpoint, seed 42. New offline predictions on recorded inputs; video/state alignment is approximate.
Final action sequence in physical units
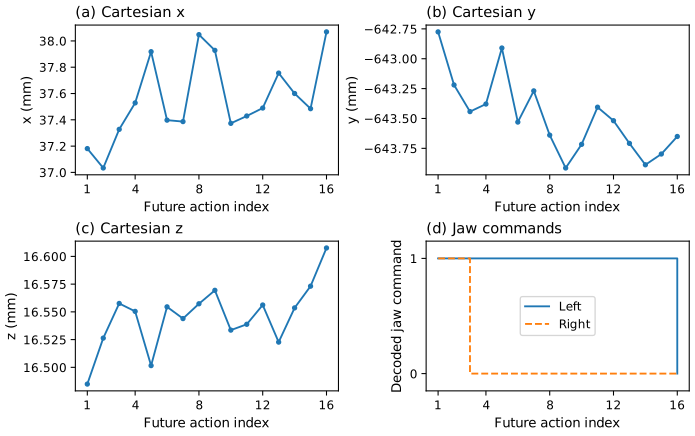
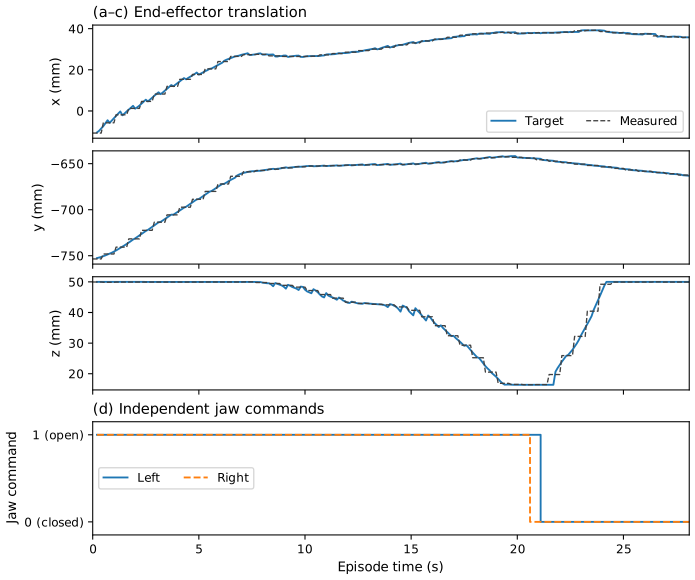
Recorded robot and jaw commands
Logged commands from episode 14. Right closure occurs at 20.6 s and left closure at 21.1 s. These values do not measure contact or force.